


Tokenizer
Comparison
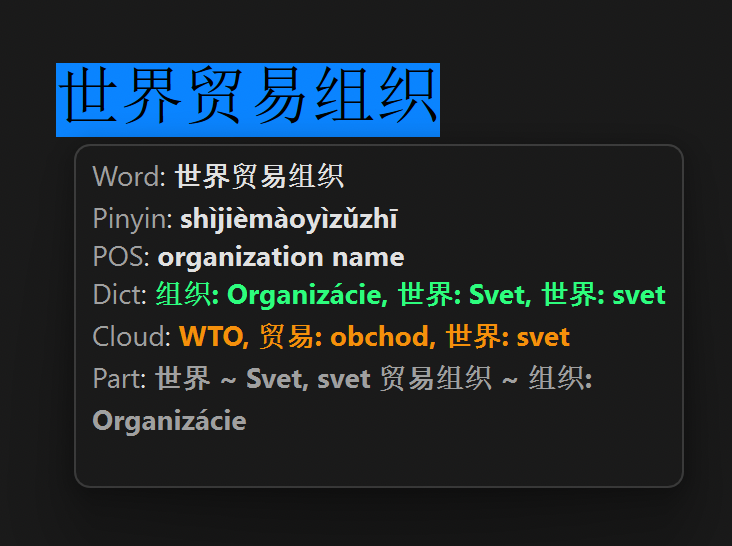
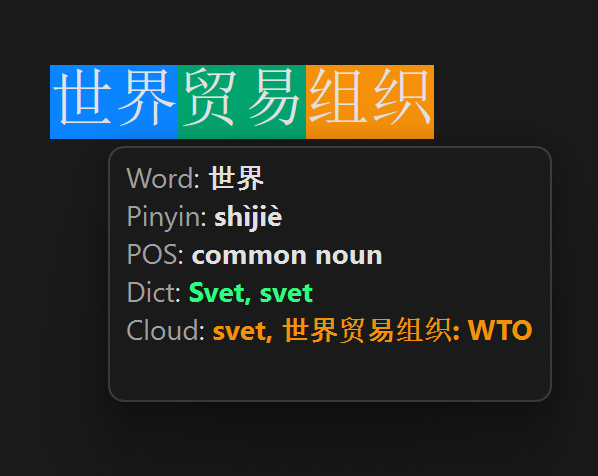
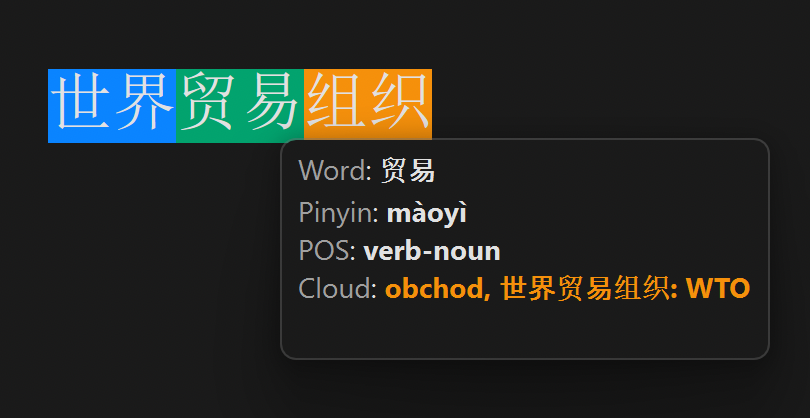
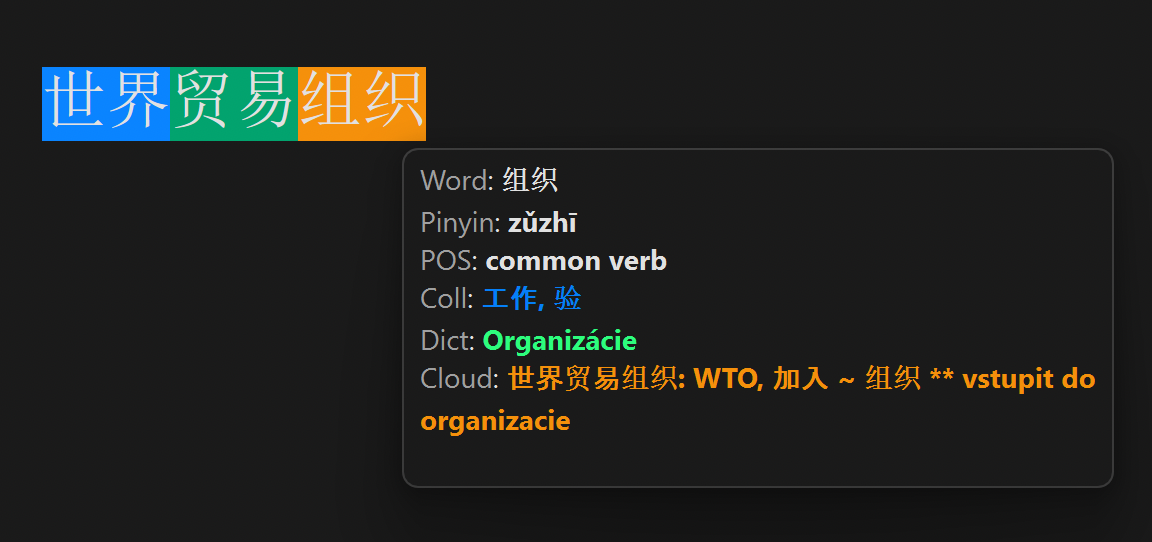
The application offers three tokenization methods:
- Jieba,
- HSK-based, and
- Single Character.
For Modern Chinese, we recommend using Jieba or the HSK-based tokenizer. The Single Character tokenizer is better suited to Literary Chinese and other written texts where character-by-character analysis is preferred.
Jieba vs. HSK-based tokenization
- Jieba generally prioritizes the longest possible sequence. As a result, it may sometimes combine characters across expected word boundaries.
- The HSK-based tokenizer identifies words using vocabulary data from the HSK framework.
The screenshots below illustrate the differences between the two methods.